

Executive Summary
The OpenTelemetry Kubernetes attributes processor reached v1.0.0 on September 16. It is the collector component that reads a pod’s namespace, node, deployment and labels and stamps them onto every metric, log and trace passing through. Without it, your telemetry arrives as a stream of numbers with no idea which workload produced them.
Stability here is a real milestone rather than a label change. It means the component meets the project’s stable criteria for testing, benchmarking, documentation and telemetry stability, and that it can be redistributed as a Go library without API breakage. It also arrives attached to the Kubernetes semantic conventions that went stable in v1.42.0 in June, so raw attribute names changed. Dashboards, recording rules and alerts that query the old names are the risk, not the upgrade itself.
OpenTelemetry just marked the least glamorous component in the collector as stable. It is also the one most teams quietly depend on.
The Kubernetes attributes processor moved to v1.0.0 and is available in the opentelemetry-collector-contrib and opentelemetry-collector-k8s distribution releases. Most people running OpenTelemetry on Kubernetes already run it without thinking about it. That is exactly why the release note matters.
One processor is why your telemetry knows what a pod is
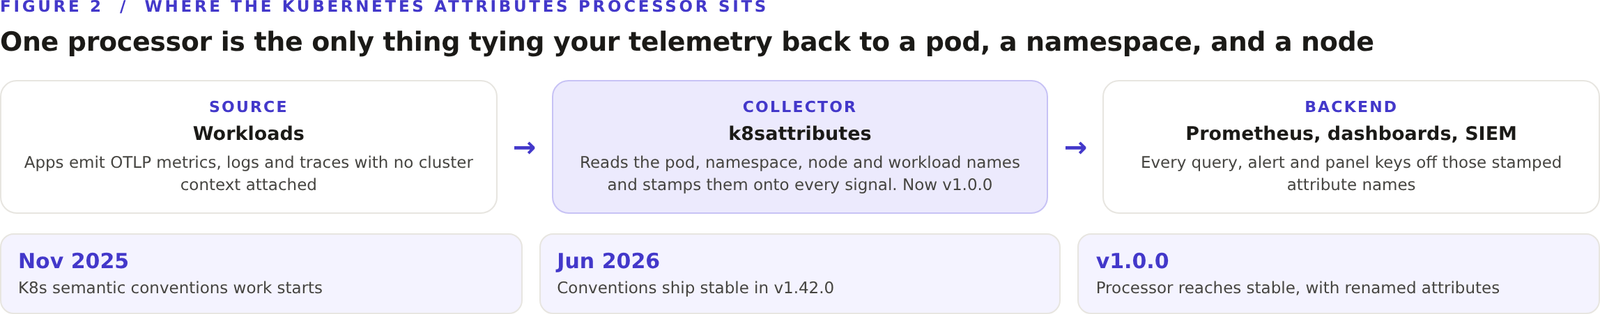
A workload emits a metric, a log line or a span. It does not attach the cluster context, because the workload usually cannot see it. The pod name, the namespace, the node, the deployment and the labels all live in the Kubernetes API, not in the process.
The processor sits in the pipeline as a DaemonSet or a deployment, watches the API, and writes that context onto every signal as it passes through. Everything downstream keys off the result. A panel that groups errors by deployment name, an alert that fires on one namespace, a cost report that splits spend by team, all of them are reading attributes this component stamped on.
That makes it a single point of failure in a way the name does not suggest. Drop it from the pipeline and the telemetry still arrives. It just stops being attributable, and every dashboard built on top of it quietly returns the wrong answer.
Stability is the project’s way of promising that the contract holds. Testing, benchmarking, documentation and telemetry stability all had to clear a bar, and the component can now be redistributed as a Go library without API breakage. That matters to anyone shipping a collector distribution, and there are a lot of them.
The upgrade is small. The attribute renames are not
The work behind this took most of a year. The Kubernetes Semantic Conventions group spotted the dependency early, started stabilizing the conventions in November 2025, reached release candidate in March 2026, and shipped stable conventions in Semantic Conventions v1.42.0 in June.
Then the processor followed, adopting the stable Kubernetes attribute names as part of the promotion work.
That last step is the one that breaks things. Attribute names are strings. A dashboard panel, a recording rule, a log query or a Grafana alert that matches on the old spelling keeps running and quietly returns nothing, or falls into an unlabeled bucket. Nothing errors. The graph just goes flat, and someone notices three days later when the alert that should have fired did not.
The project shipped a migration guide alongside the release for exactly this reason. If you maintain a collector config that touches Kubernetes enrichment, read it before you bump the image tag. The changelog for the component is short. The downstream diff is not.
What to check before you bump the collector
Four things, in order. Find every query that filters on a Kubernetes resource attribute, including the ones hiding inside dashboard variables, saved log searches and alert rules. Grep for the old names rather than reading panels by eye, because the ones that break are the ones nobody opens.
Next, check whether you run a vendor distribution rather than upstream contrib. Distributions pin their own component versions, and some will carry the rename before you expect it. Then check your sampling and processor order. If the processor sits behind a sampling stage, a name change can move which spans survive and which get dropped.
Last, treat the promotion as good news you can use. A stable component is a safe thing to standardize on, and OpenTelemetry has been clear that more components are going through the same process under the Stable by Default effort the Collector SIG started in late 2025. The collector project is heading toward its own v1 distribution, and components like this one are the groundwork.
The component that tells your telemetry what it is looking at just became a supported contract. Make sure your queries still speak the same language before you find out the hard way.
Related reading. We covered why OpenTelemetry graduation mattered more than it sounded, what v1.37 did to native histograms, and why the container runtime wars are already over.
Get the next one before it is old news
Independent analysis of cloud-native infrastructure, Kubernetes and data centre economics. No vendor spin.