
Get the full report
One email and the rest of the report opens, plus the weekly roundup. No vendor spin, unsubscribe anytime.
Enterprise AI Infrastructure Runs on Four Layers. Most Break Below the Model.
Hardware, operating system, cloud native, and development. What each layer has to do, and where enterprise deployments break.
Executive Summary
AI infrastructure is now the biggest capital cycle in enterprise technology. IDC counted 89.7 billion dollars of it in the first quarter of 2026 alone and raised its full-year forecast to 497 billion. Gartner puts worldwide AI spending at 2.52 trillion this year, up 44 percent. Moody’s expects the six largest hyperscalers to spend 785 billion on capital projects in 2026, near a trillion in 2027. Analysts differ on timing and on returns. They agree on the direction.
The contracts show what buyers believe. Deals are signed in gigawatts now, not chips. OpenAI and Broadcom committed to 10 gigawatts of custom accelerators. Anthropic expanded its Google and Broadcom deal to about 3.5 gigawatts. AMD and Meta agreed to 6 gigawatts. Every large buyer is adding a second supplier and designing its own silicon. That is the tell. The constraint has moved off silicon. Power, drivers, and scheduling now decide how much of that capacity ever gets used, and enterprises lose more value in those three places than they ever lose on model quality.
Most enterprise AI programs do not fail on the model. They fail on the four layers underneath it. This report walks each one, says what it has to do, and names the specific way it tends to break.
1. The stack is four layers, and the bottom one sets the ceiling
2. Hardware no longer fits a normal room
3. The operating system is where quiet failures live
4. One GPU pool, many teams
5. Development is the loop that keeps the rest honest
6. What to do first
The stack is four layers, and the bottom one sets the ceiling
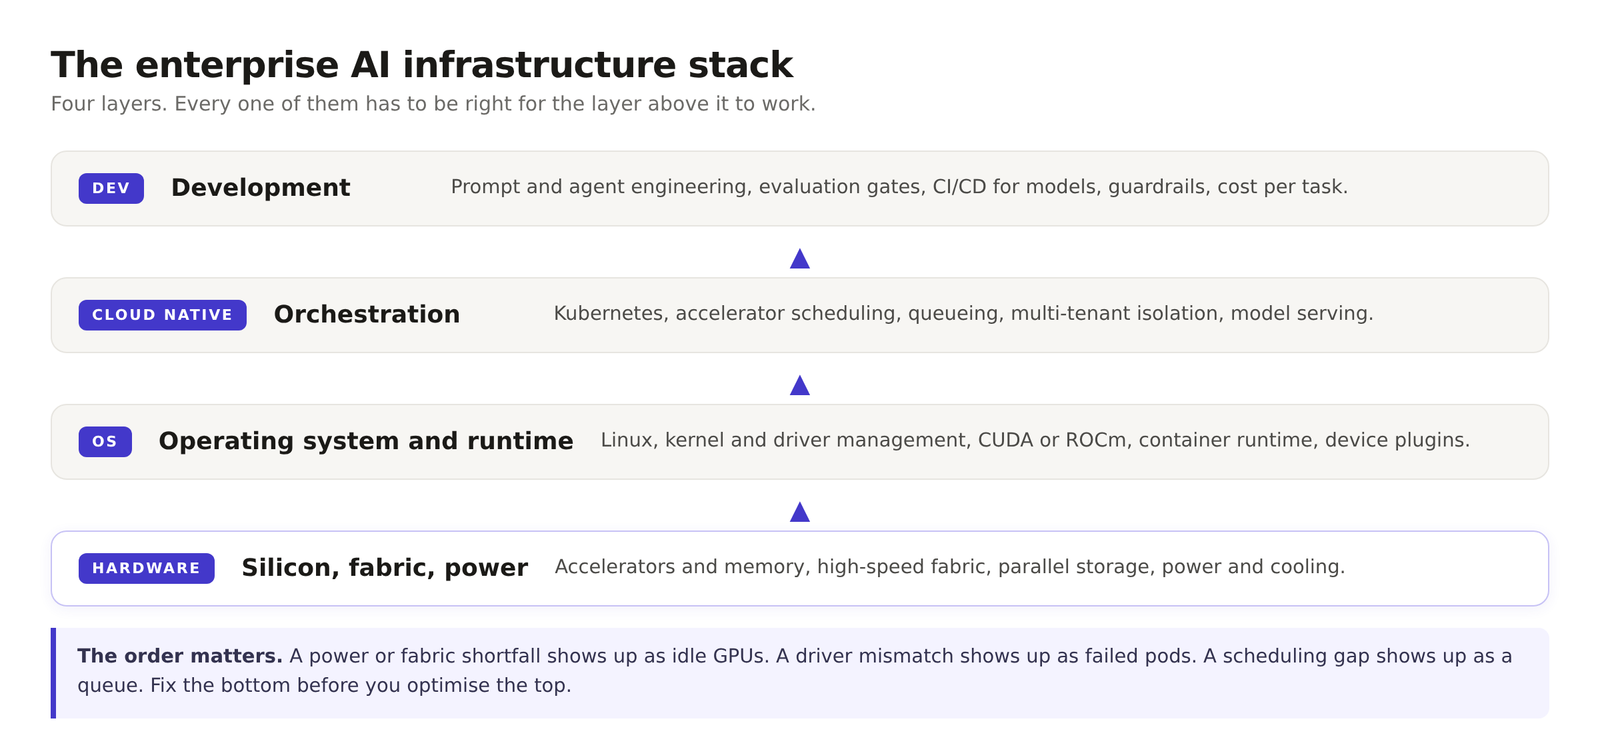
Think of an AI platform as an assembly problem. Four layers sit under your application, and each one constrains the one above it. Hardware gives you accelerators, fabric, storage, and power. The operating system and runtime put a stable, containerized face on that silicon. Cloud native orchestration decides which workload gets which accelerator, and when. Development is how a model turns into a service with a name on it, an evaluation gate, and a cost line.
The order matters more than most teams admit. A power or fabric shortfall shows up as idle accelerators. A driver mismatch shows up as pods that refuse to start. A scheduling gap shows up as a queue. Fix the top layer while the bottom is broken and you have bought yourself a nicer interface on a bottleneck.
Hardware no longer fits a normal room
Continue reading
Read the AI Infrastructure report
You have read the first two sections. Tell me where to send the rest and it opens right here. No spam, unsubscribe anytime.
Your existing data center was built for CPU workloads that sip power and tolerate millisecond latency. AI breaks all of that at once. One GPU node can pull more power than a whole traditional rack, and the fabric has to deliver sub-microsecond latency to keep very expensive accelerators from sitting idle.
The hardware market reflects it. NVIDIA’s GB200 NVL72 links 72 accelerators into one coherent domain. AMD’s Instinct line and Intel’s Gaudi push the same way from different starting points, and the hyperscalers design their own silicon. Your practical question is much narrower than the spec sheets suggest.
For inference, memory bandwidth and capacity decide what fits and how fast it answers. Peak throughput wins the headlines. A model that does not fit in memory does not run at all, and one that fits badly runs slowly no matter how fast the arithmetic is.
| Dimension | Traditional server | AI GPU server |
|---|---|---|
| Power per rack | 5 to 15 kW | 40 to 120 kW |
| Cooling | Air | Liquid, rear-door, or immersion |
| Network | 10 to 100 GbE | 400 GbE or NDR InfiniBand |
| Storage throughput | 1 to 10 GB/s | 100 to 1,000 GB/s parallel |
| Cost per node | $5K to $50K | $150K to $400K and up |
| Operational skill | General IT | Specialized AI and HPC engineers |
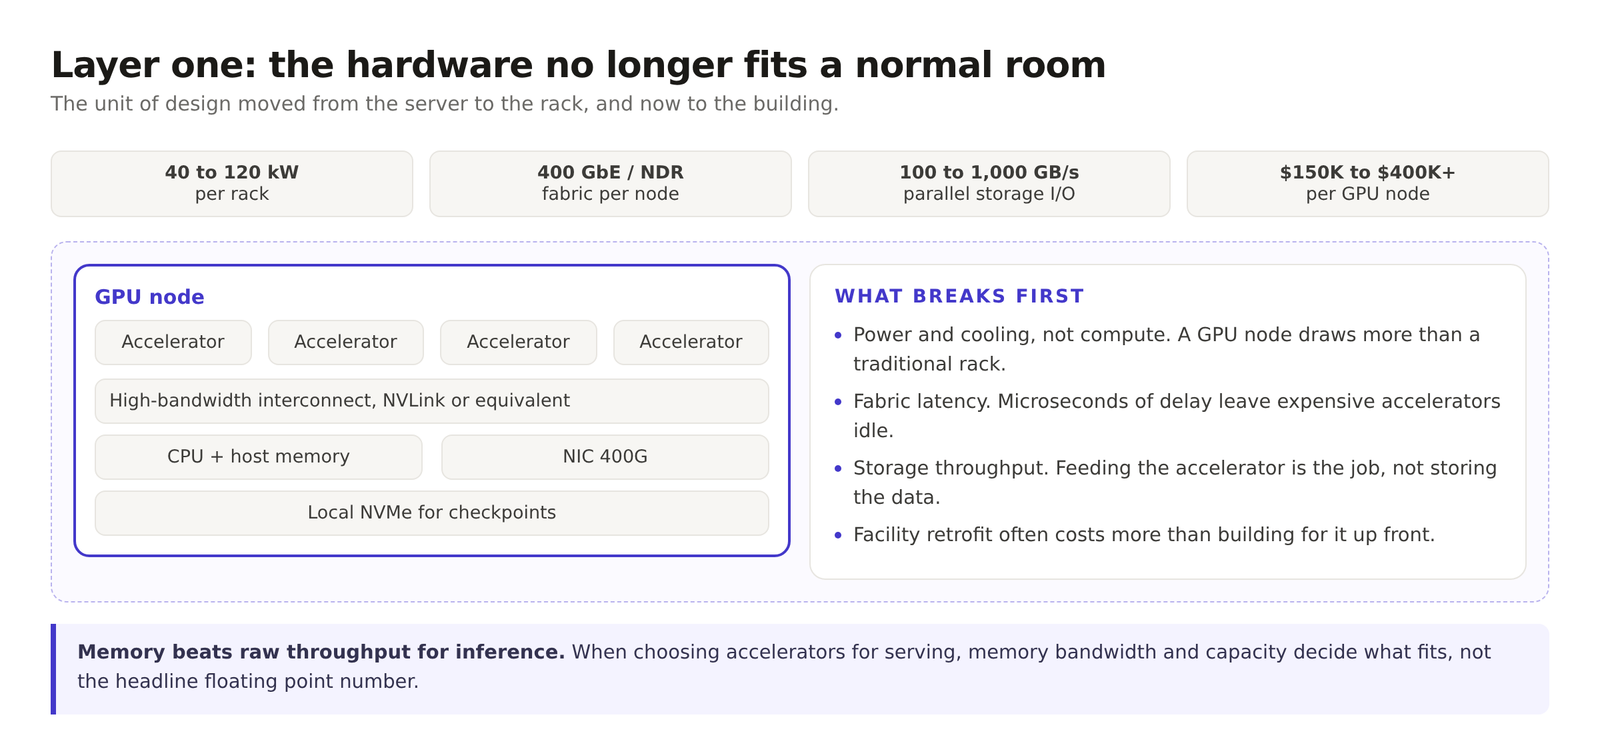
The expensive mistake is dropping accelerators into a facility built for traditional IT. Power circuits, thermal limits, and network bottlenecks then pin your utilization in the single digits, and retrofitting costs more than designing for it up front.
The operating system is where quiet failures live
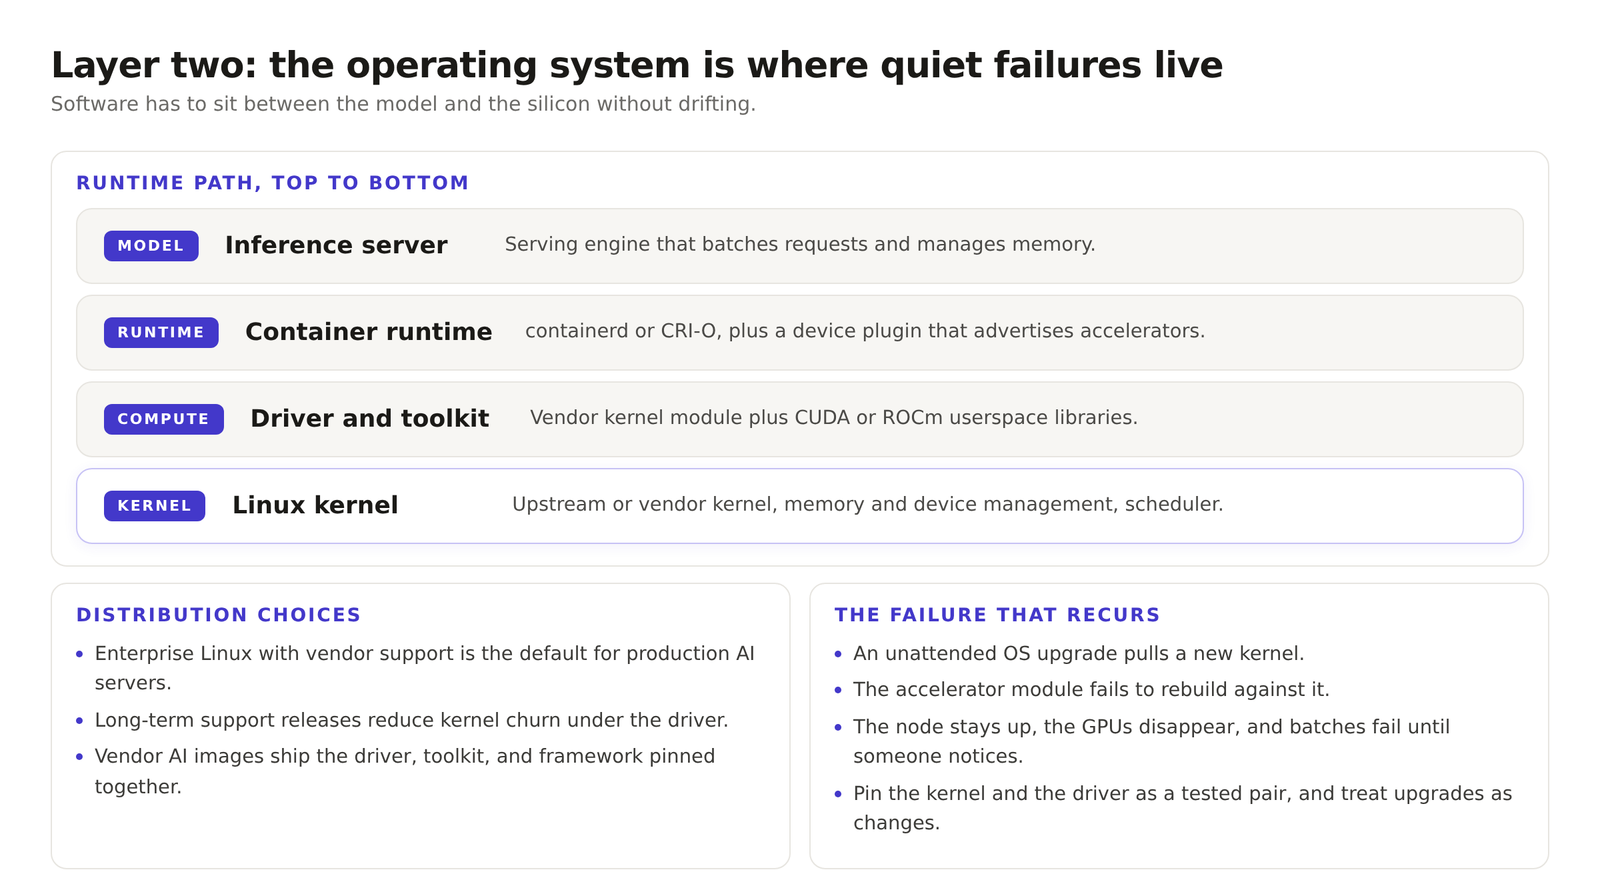
Between your model and the silicon sits a software path that has to stay aligned. The serving engine runs in a container. The container runtime, usually containerd or CRI-O, uses a device plugin to advertise accelerators. Under that, a vendor kernel module and a userspace toolkit expose the hardware. At the bottom, the Linux kernel handles memory, devices, and scheduling.
Enterprise Linux still runs most production AI servers, because long-term support releases reduce kernel churn under the driver. Vendors now ship AI images with the driver, toolkit, and framework pinned together, which removes a whole class of integration bugs. Red Hat Enterprise Linux AI bundles an inference server and fine-tuning tooling into the platform. SUSE pairs its enterprise Linux with Rancher Prime and validated blueprints on top. The pattern is the same everywhere. Pin the stack, hand over a tested combination.
The failure that keeps happening is boring and expensive. An unattended OS upgrade pulls in a new kernel. The accelerator module fails to rebuild against it. The node stays up, the accelerators vanish, and batches fail until somebody notices. Treat the kernel and driver as one tested pair, and treat upgrades as changes with a rollback plan.
One GPU pool, many teams
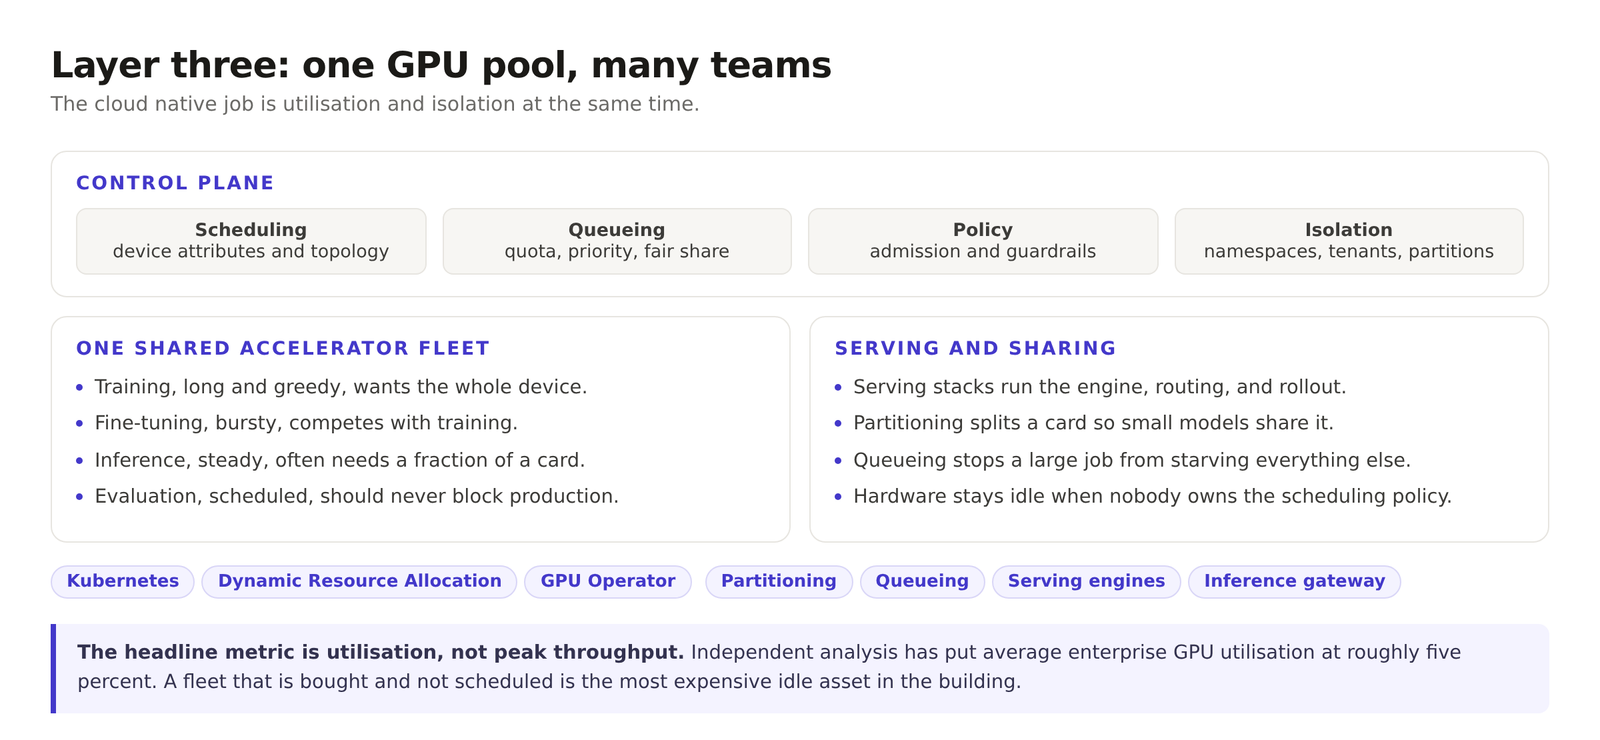
An AI factory is a pool of accelerators that many teams pull from at once. One team fine-tunes. Another serves inference. A third runs evaluations. All on the same hardware. Training a model is no longer the hard problem. The hard problem is giving every team safe, isolated access to one expensive fleet without anyone standing on anyone else.
Kubernetes supplies most of the parts. Kubernetes 1.34 moved Dynamic Resource Allocation to stable, which lets the scheduler reason about devices by attribute and topology instead of a plain count. The NVIDIA GPU Operator handles drivers and device advertising. Kueue and Volcano add quotas, priority, and fair sharing. vLLM and KServe wrap routing, rollout, and scale to zero.
The trap is the resource model. A pod that asks for one whole accelerator pins that device even when it barely uses it. To keep tenants apart, platforms hand each team a dedicated cluster or a dedicated block of accelerators. Safe, and it wastes most of the capacity. Slicing a card into isolated partitions helps, but only when the workload matches the slice. None of this fixes itself. Utilization is a scheduling and policy decision, not a property of the hardware.
| Workload | Shape | What it needs |
|---|---|---|
| Training | Long, greedy, wants the whole device | Gang scheduling, topology awareness, checkpoint storage |
| Fine-tuning | Bursty, competes with training | Queueing and preemption so it does not starve |
| Inference | Steady, often needs a fraction | Partitioning, fast model load, gateway routing |
| Evaluation | Scheduled, must not block production | Separate quota and priority class |
What buyers judge is the wrapper around the accelerators. SemiAnalysis ClusterMAX rates GPU clouds across ten categories, including security, networking, storage, and reliability, and rewards hard per-tenant isolation over peak throughput. Hold your internal platform to the same bar.
Development is the loop that keeps the rest honest
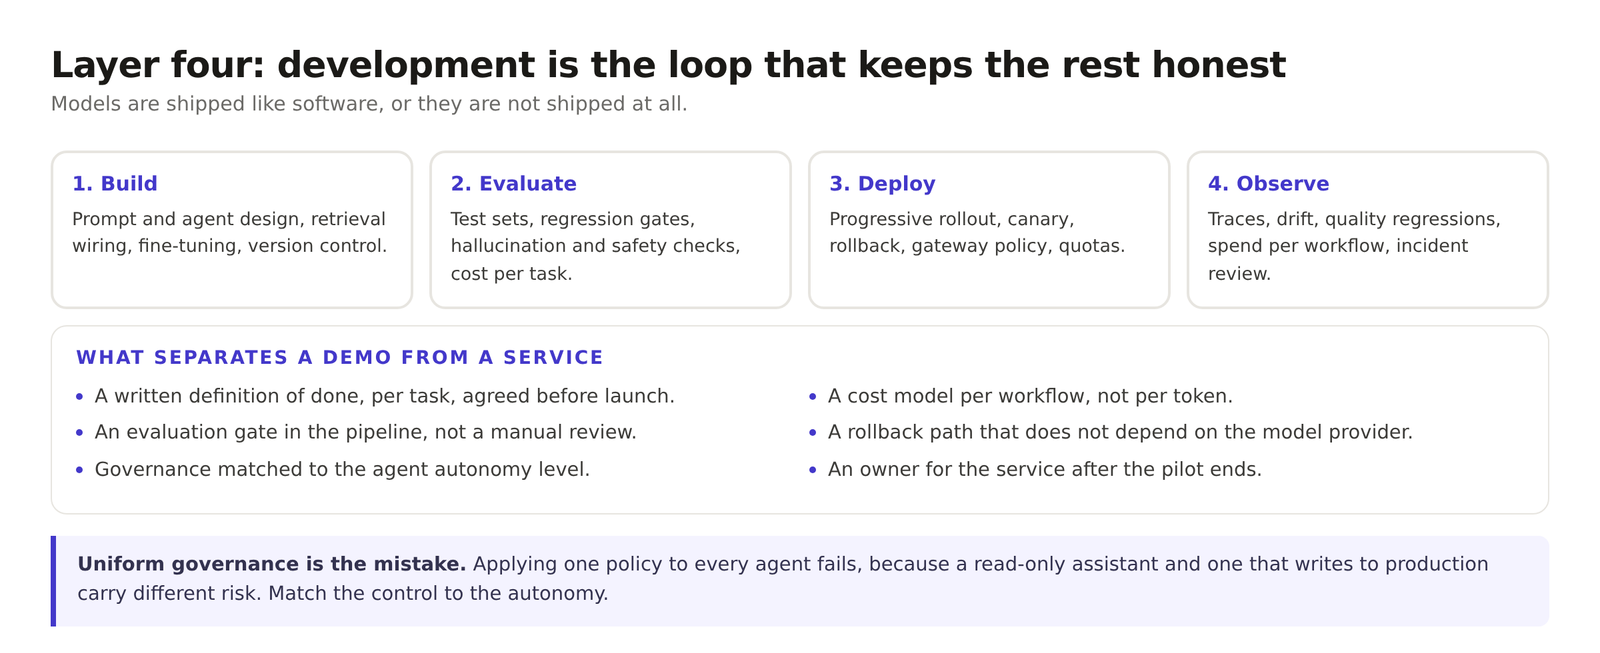
The development layer is how a model becomes a service. Build covers prompt and agent design, retrieval, fine-tuning, and version control. Evaluate covers test sets, regression gates, and cost per task. Deploy covers progressive rollout, canary, and rollback. Observe covers traces, drift, quality regressions, and spend. Break any one link and your platform starts shipping surprises.
This is where enterprise practice has moved fastest. Coding agents are now their own product category. One uniform policy for every agent does not work, because a read-only assistant and an agent that writes to production carry very different risk. Gartner expects 40 percent of enterprises to demote or retire autonomous agents by 2027, after governance gaps surface in an incident. Match the control to the autonomy level.
The other correction is what you measure. Token price keeps falling. The cost of the workflow does not, because an agentic task burns orders of magnitude more tokens than a chat turn, and every step compounds. Gartner expects the cost per agentic workflow to rise more than fivefold by 2028. Budget per workflow, not per token.
| Practice | Demo | Service |
|---|---|---|
| Definition of done | It looked good in the room | Written per task, agreed before launch |
| Quality gate | Manual review | Evaluation gate in the pipeline |
| Governance | One policy for everything | Control matched to autonomy level |
| Cost model | Per token | Per workflow and per task |
| Ownership | The pilot team | A named service owner |
What to do first
Start from the floor, not the ceiling. Settle the power, cooling, fabric, and storage envelope before you commit to a number of accelerators. Those four decide the utilization you can actually reach. Then pin the OS, driver, toolkit, and framework as one tested set, and put a change process around it. That removes the most common silent outage.
Then attack utilization. The dashboard number is allocation, not work. Measure what the accelerators actually do, then find where the idle hours hide. Nightly jobs that reserve cards all day and training runs that finish and leave nodes warm are where better scheduling pays for itself. Only after that does the serving stack matter, and by then the choice is easier because you know the workload shape.
Finish with the development loop, because it is the layer that keeps the platform honest. Put an evaluation gate in the pipeline, match governance to autonomy, and measure cost per task. A platform that cannot tell you what it costs to answer a question is not managed. It is funded.
Related reading. The 2026 State of Enterprise Infrastructure covers the wider market behind these layers. The VMware migration wave, the data center power crunch, sovereignty, platform engineering, and supply chain security.
Analyst spending and cost forecasts come from public announcements by IDC on AI infrastructure spending, Gartner on worldwide AI spending and agentic inference costs, and Moody’s Ratings on hyperscaler capital spending. Deal sizes come from the OpenAI and Broadcom announcement, Broadcom’s expanded Anthropic agreement, and the AMD and Meta agreement. The 5 percent GPU utilization figure comes from Cast AI’s 2026 State of Kubernetes Optimization Report. No analyst endorsement of any vendor is implied.
Platform detail draws on a CNCF post on building an AI factory on Kubernetes, the Kubernetes documentation on Dynamic Resource Allocation, Gartner’s research on agent governance, SemiAnalysis ClusterMAX, a Mirantis overview of the AI infrastructure stack, and vendor material from Red Hat and SUSE. Figures on rack power, storage throughput, and node cost are representative industry ranges, not a single vendor specification.