

Executive summary
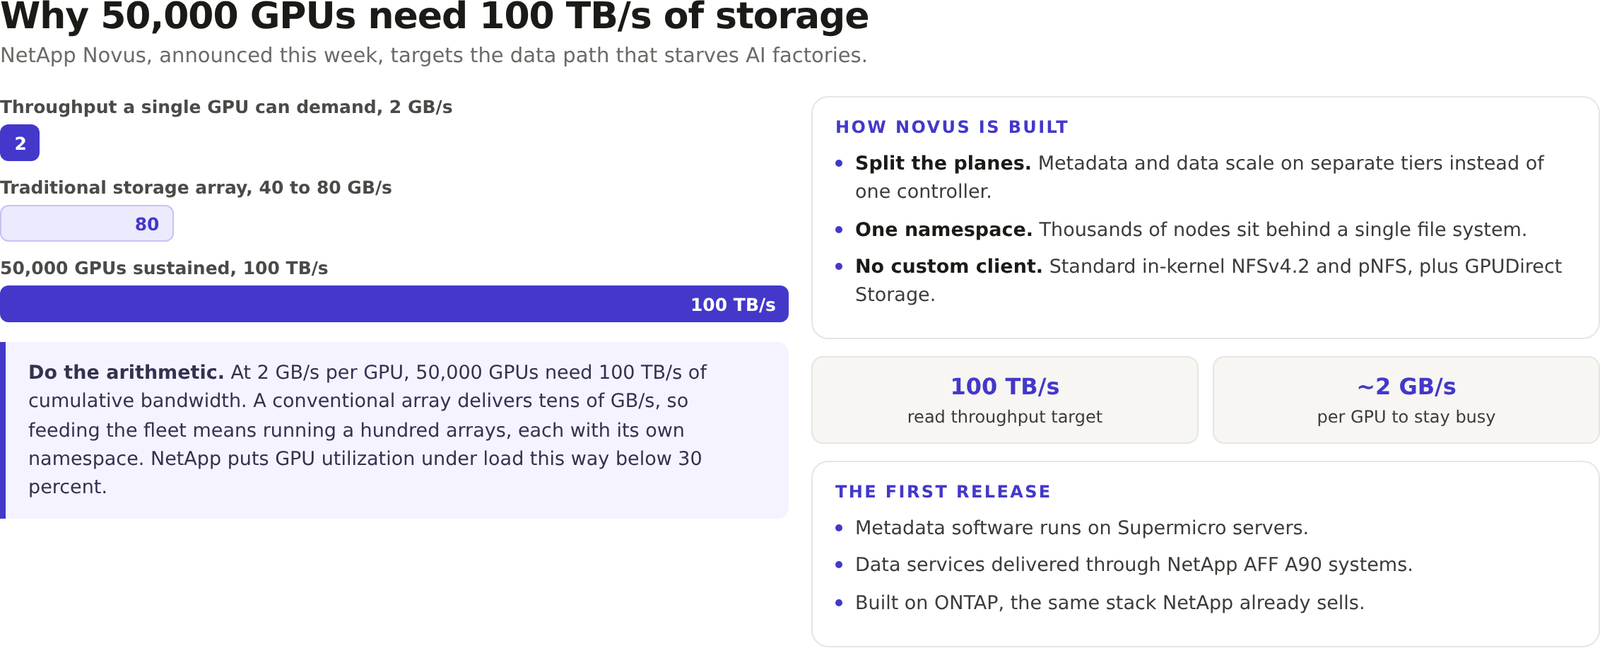
NetApp announced Novus this week, a storage architecture that splits metadata from the data path so throughput and capacity scale on separate tiers under one namespace. The pitch rests on one number. A single GPU can demand about 2 GB/s to stay busy, so a 50,000 GPU AI factory needs roughly 100 TB/s of aggregate bandwidth, while a conventional array delivers tens of GB/s.
The finding is what that does to the economics. NetApp puts GPU utilization under a starved data path below 30 percent, and the accelerator is the largest capital item in the building and the only one that earns revenue. The throughput figure is a vendor claim that no independent benchmark has reproduced. Watch the operator results, not the launch number.
An AI factory has one asset that makes money, and it is the GPU. Everything around it is a cost. NetApp Novus, announced this week, rests on a claim about where the bottleneck now sits, and it is not the chip. It is the path that feeds it.
The architecture separates metadata from data movement so the two scale independently, then unifies thousands of storage nodes behind a single namespace. NetApp says the design exceeds 100 TB/s of aggregate read throughput and keeps hundreds of thousands of GPUs productive. The first release runs NetApp’s metadata software on qualified Supermicro servers and delivers ONTAP data services through NetApp AFF A90 arrays.
Storage starvation shows up as idle GPUs, not slow disks
The arithmetic reframes the problem. NetApp’s own figure is that a single GPU can pull about 2 GB/s to stay productive. Run that across 50,000 GPUs and the fleet needs roughly 100 TB/s of cumulative bandwidth. A traditional storage array delivers tens of GB/s. Closing the gap with conventional arrays means deploying more than a hundred of them, each with its own namespace and its own failure domain, then moving data between them.
When the path cannot keep up, the GPUs wait. NetApp puts utilization below 30 percent in that condition, and a GPU that is waiting is depreciating without producing. The storage shortfall stops being a performance note and becomes a margin line.
The design choice is to split metadata from the data path
Most arrays scale metadata and data together, because one controller manages both, and that coupling sets the ceiling. Novus puts metadata on its own tier and data on another. An operator can grow capacity without dragging the data path with it, or grow throughput without recomputing the namespace.
The client side is deliberately ordinary, and that is the useful part. Novus uses standard in-kernel NFSv4.2 and pNFS with GPUDirect Storage, so there is no proprietary agent to install across thousands of GPU servers. A custom client on every node adds an operational bill that arrives on upgrade day, when kernels and accelerator generations change.
The throughput figure is a vendor number until someone reproduces it
100 TB/s is NetApp’s claim, modelled against testing the company says it observed. No independent benchmark of Novus at full scale is public. Treat the figure as a design target and ask a narrower question. Does the architecture hold throughput when the namespace is large, the tenants are noisy and the read pattern is not sequential.
That matters because the storage market is crowded with AI-era claims, and the buyers are the same neoclouds and GPU-as-a-service providers choosing between them. The product is real and the arithmetic is directionally right. Whether a single file system at zettabyte scale behaves the way the launch describes is the part a reference customer will settle.
Three questions before you size storage against a fleet. What is your measured GPU utilization when the data path is loaded, not idle. What happens to throughput when ten tenants read at once. And can you add capacity without changing what the clients mount.
Related reading. Our report on the four layers under the model places storage in the wider AI stack, and we looked at the power side of the same buildout.
Sources. AFP and Benzinga carried the announcement, Zawya reported it the following day, and Engineering.com covered the Supermicro side. The NVIDIA GPUDirect Storage documentation explains the direct path from storage to accelerator memory.
Get the next one before it is old news
Independent analysis of cloud-native infrastructure, Kubernetes and data center economics. No vendor spin.