

Executive Summary
OpenAI and Anthropic cut prices on the same evening, and the cuts landed on different parts of the bill. OpenAI shipped GPT-6 Sol and GPT-6 Luna on 22 September and halved both rates, taking Sol to 2 dollars per million input tokens and 10 dollars per million output, and Luna to 10 cents and 50 cents. Anthropic released Claude Opus 5.5 the same day at 4 dollars and 20 dollars per million, with cache reads down 60 percent to 20 cents. The finding is that the headline rate no longer decides the money. Cached input sits at a tenth of the uncached rate on OpenAI’s card, and Anthropic says cache reads are the majority of agentic and coding work costs. Miss the cache and you pay full recompute.
The pattern is a price floor set by serving efficiency rather than model quality. Artificial Analysis measured it in cost per task instead of cost per token, and GPT-6 Sol at maximum effort runs its Intelligence Index for 1.06 dollars against 1.99 dollars for GPT-5.6 Sol, while Luna drops to 7 cents from 18. The labs are competing on how much of a repeated prompt they can avoid recomputing.
Inference cost per token fell by half in a single night, and the reason has almost nothing to do with the models. Two labs repriced on the same day and leaned on the same mechanism. Caching.
OpenAI’s model page for GPT-6 Sol lists 2 dollars per million input tokens, 20 cents for cached input, 2.50 dollars for cache writes and 10 dollars per million output tokens. That is half the rate of GPT-5.6 Sol on both input and output. GPT-6 Luna goes to 10 cents input and 50 cents output, against 20 cents and 1.20 dollars before. Anthropic’s Claude Opus 5.5 announcement puts input at 4 dollars and output at 20 dollars per million, with cache reads at 20 cents rather than 50, and claims a 40 percent drop in the cost to run typical workloads.
Cached input is priced at 10 percent of the uncached rate. That single ratio turns prompt structure into a procurement decision. A prefix that repeats is cheap. A prefix that does not repeat is billed at full rate and recomputed on every call.
Input tokens were never the expensive part
GPT-5.6 Sol at 4 dollars input and 20 dollars output made the asymmetry obvious. Output cost five times input, so every optimization that shortened a response saved more than one that shortened a prompt.
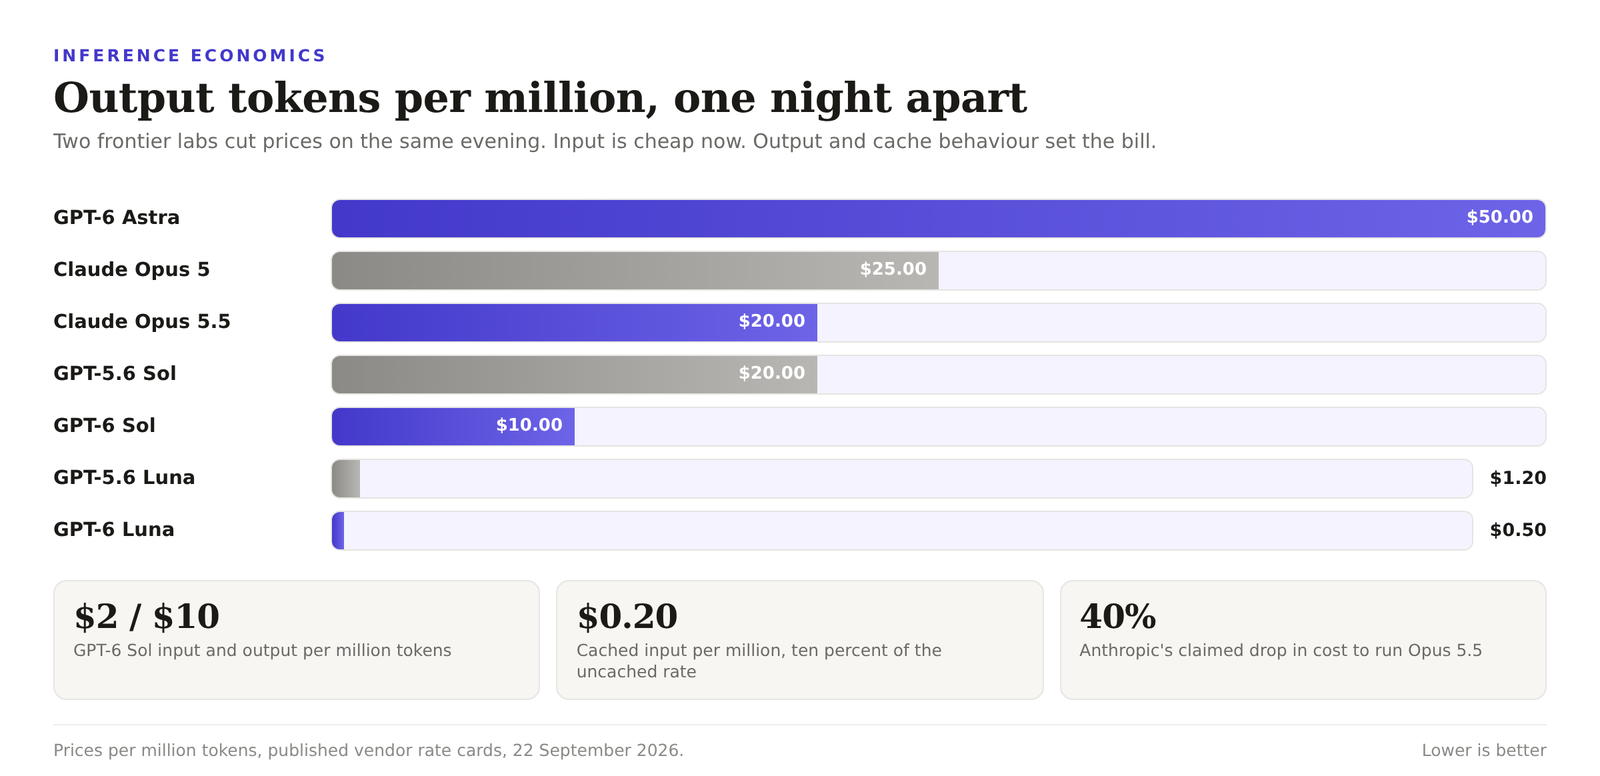
GPT-6 Sol does not narrow that ratio. It is 2 dollars in against 10 dollars out, still a factor of five. What changed is the absolute floor. When output costs 10 dollars per million rather than 50, the case for a smaller self-hosted model weakens as the case for better caching strengthens.
A cache miss is a recompute, and recompute is the tax
A cache miss on a prefix is not just a billing line. That is where a model release becomes an infrastructure problem. It is a full prefill of tokens the cluster already processed. On a GPU that is already power-limited, that is capacity spent re-deriving something that existed minutes ago.
The serving stacks have said this for months. vLLM shipped tiered KV cache offloading in v0.22 and published the scaling evidence in September. Below roughly 64 concurrent conversations the working set fits in HBM. Between 64 and 128 the cache fills and throughput drops sharply without offloading. Past 128, host memory fills too, and a storage-backed tier more than doubles throughput. At scale the choice is between a storage-backed cache hit and a full recompute, and storage wins.
Vendors cut the price of a cache hit to a tenth of a fresh token while shipping tooling that makes a cache hit survive beyond one GPU. The cheap tier is where the volume wants to move.
The cheap tier is where the volume moves
Look at the bottom of the price list rather than the frontier. GPT-6 Luna at 50 cents per million output tokens is priced below most open weight deployments once you count the GPU hours to serve them. That changes the build versus buy conversation for classification and routing work, quietly.
Artificial Analysis also caught the trade. Both GPT-6 models regressed on some knowledge work evaluations while their hallucination rates fell sharply, Sol from 92 percent to 60 percent. Cheap and more careful is a different buying decision than cheap and worse quality.
The wrong takeaway is that inference is solved. The right one is that the marginal cost of a repeated token fell through the floor, and the marginal cost of a novel one did not.
Three questions to ask about your own inference stack. What share of your prompt tokens are cache hits, and do you measure it? If a model’s cache read price dropped 60 percent, would your architecture collect it? And who owns the cache tier, the application team or the platform team?
Related reading. Anthropic Leased 2.16 Gigawatts in Australia, and It Is Inference Only. Here. Round-Robin Routing Wastes GPUs. AWS Just Made the Open Fix an EKS Add-On. Here.
Rate cards come from OpenAI’s GPT-6 Sol model page, the OpenAI pricing table and Artificial Analysis.
Get the next one before it is old news
Independent analysis of cloud-native infrastructure, Kubernetes and data center economics. No vendor spin.
[…] price falls, because the machine does more work in the hour it is rented. Our earlier look at the inference price war and cache economics covers the throughput […]
[…] floor under the whole exercise is memory and power, not raw compute. We made that case when token prices halved in a single night and the bill moved into the cache. NVIDIA Dynamo, the open source serving framework behind […]
[…] reading. We broke down why the topology of a GPU cluster decides what the scheduler can do, and why token prices keep moving once caching enters the picture. The full detail is in Google’s Pod snapshot […]
[…] the mix of prefill to decode decide what a token actually costs, which is the argument behind our token price and cache analysis. Anthropic’s own CPU heavy deal with Akamai shows the same logic, that not every stage of an […]