

Executive Summary
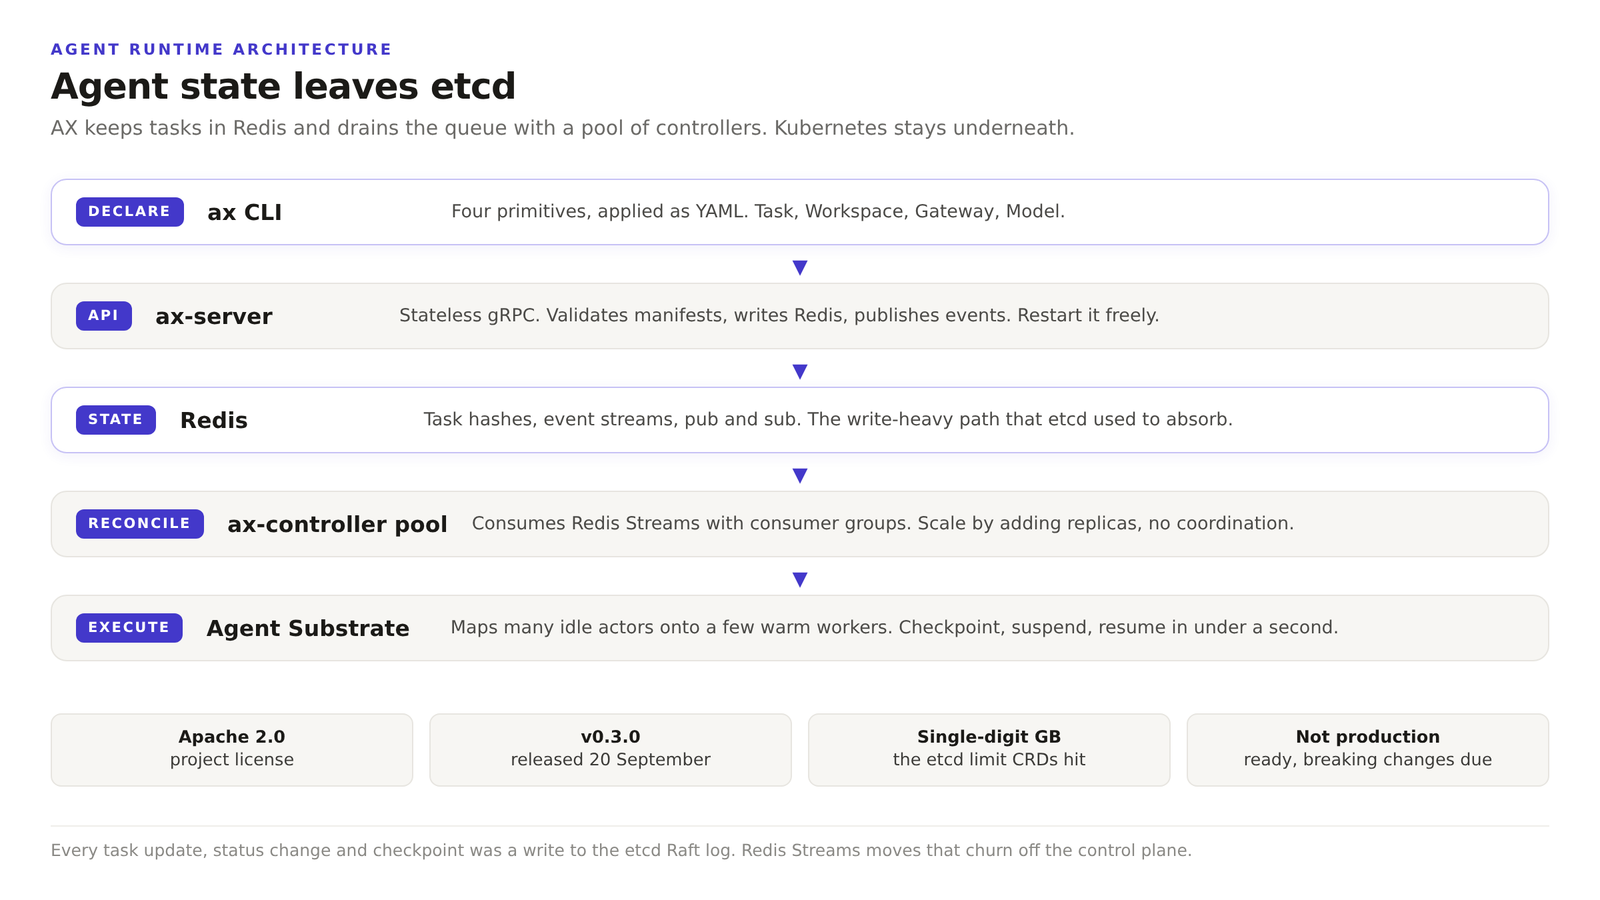
Google’s open-source AX project shipped version 0.3.0 on 20 September with one architectural decision that matters more than the feature list. Agent task state no longer lives in Kubernetes. The project’s own design document says storing millions of short-lived tasks as custom resources pushes etcd past its comfort zone, naming single-digit gigabyte storage limits, write-rate bottlenecks, and control plane degradation. AX keeps that state in Redis and drains a Redis Streams queue with a horizontally scaled pool of controllers.
The lesson is not that Redis beats etcd. It is that agents are a high-churn workload the standard Kubernetes control plane pattern was never sized for, and the industry is now routing around it. Google’s answer is still alpha, explicitly not production ready, and depends on a new Redis tier with no documented failover. Read the argument before you copy the code.
Google published AX v0.3.0 on 20 September. AX stands for Agent Executor, an Apache 2.0 runtime for running large fleets of AI agents. The release note itself is unremarkable. The design document behind it is not.
AX sits on top of Agent Substrate, the runtime Google shipped alongside its agent sandbox work. Substrate maps a large set of mostly idle agents onto a small set of warm workers and suspends the rest to storage. That solves the compute problem. It does nothing about where the task records live.
etcd was never a queue
Every Kubernetes custom resource is a row in etcd. Every status transition is a write to the etcd Raft log. At the volume of a normal platform that is invisible. At the volume of an agent fleet it is the entire problem.
The AX design document states it plainly. Storing millions of short-lived tasks as CRDs pushes etcd past its comfort zone, listing single-digit gigabyte storage limits, write-rate bottlenecks, and control plane degradation. That last one is the expensive failure mode. Fill the etcd write path with agent chatter and every other controller in the cluster starts missing its reconciliation loop.
AX routes around it. The ax-server is a stateless gRPC service. It validates a manifest, writes it to Redis, and publishes an event. Task hashes, event streams, and pub and sub channels all live in Redis. A pool of ax-controller workers consumes the stream using consumer group semantics, so a failed controller’s pending messages get redelivered to another. Scaling that pool is a replica count change. No coordination, no leader election.
That is a work queue doing the job of a reconciliation loop. It is also a new dependency. Redis now sits in the critical path of every agent task, and the design document does not describe replication or failover for it. Anyone who has operated Redis at volume knows what that gap can cost.
The four primitives are the interesting half
The state move gets the attention. The primitives are what make the thing buildable. AX gives you Task, Workspace, Gateway, and Model, each declared in YAML against the ax.io/v1alpha1 API group.
A Task is the smallest unit of isolated execution. A Workspace is the environment, resolved once and bound from as many tasks as needed. It can list git repositories, MCP servers, and skills, or take a plain-language goal and let an agent finish the setup on first boot. A Gateway is the network boundary, an egress allowlist of hosts and ports plus credential injection. A Model is a named model configuration, so rotating a key is one apply instead of an edit in every task definition.
The RPC surface tells you what Google thinks agent lifecycle is. SuspendTask and ResumeTask are first-class operations, not pod restarts. An agent waiting on a model response, a tool call, or a human approval gets checkpointed, and its state survives the transition. That is a different contract from deleting a pod and hoping the workload can rebuild itself.
Read it as a warning, not a shopping list
You do not need AX to take the lesson. If you are storing agent job records as CRDs in a cluster that also runs your platform, you have put a high-churn queue inside the one datastore that degrades the whole control plane when it fills up. The fix is boring. Keep the durable record somewhere built for write volume and let the cluster reconcile the work it is actually good at.
Two caveats before anyone ships this. AX v0.3.0 is an alpha, the project says breaking changes are coming, and external pull requests are paused while the core is stabilised. The performance claims, including the density figures, are Google’s own and carry no published benchmark methodology.
The direction is still the story. Google wrote a large part of Kubernetes, and it is now telling platform teams that the CRD-and-etcd pattern is the wrong shape for agents. When the authors of a pattern start routing around it, the pattern is the news.
Related reading. Our coverage of Agent Substrate on Google Kubernetes Engine explains the compute layer underneath. The managed agent harness question is the layer above. And for the same argument from the scheduler side, see Kubernetes 1.37 rebuilding for accelerators.
Get the next one before it is old news
Independent analysis of cloud-native infrastructure, Kubernetes and data center economics. No vendor spin.
[…] Related reading. Our case for giving an agent’s permissions to the image it runs, and why agent state does not belong in etcd. […]